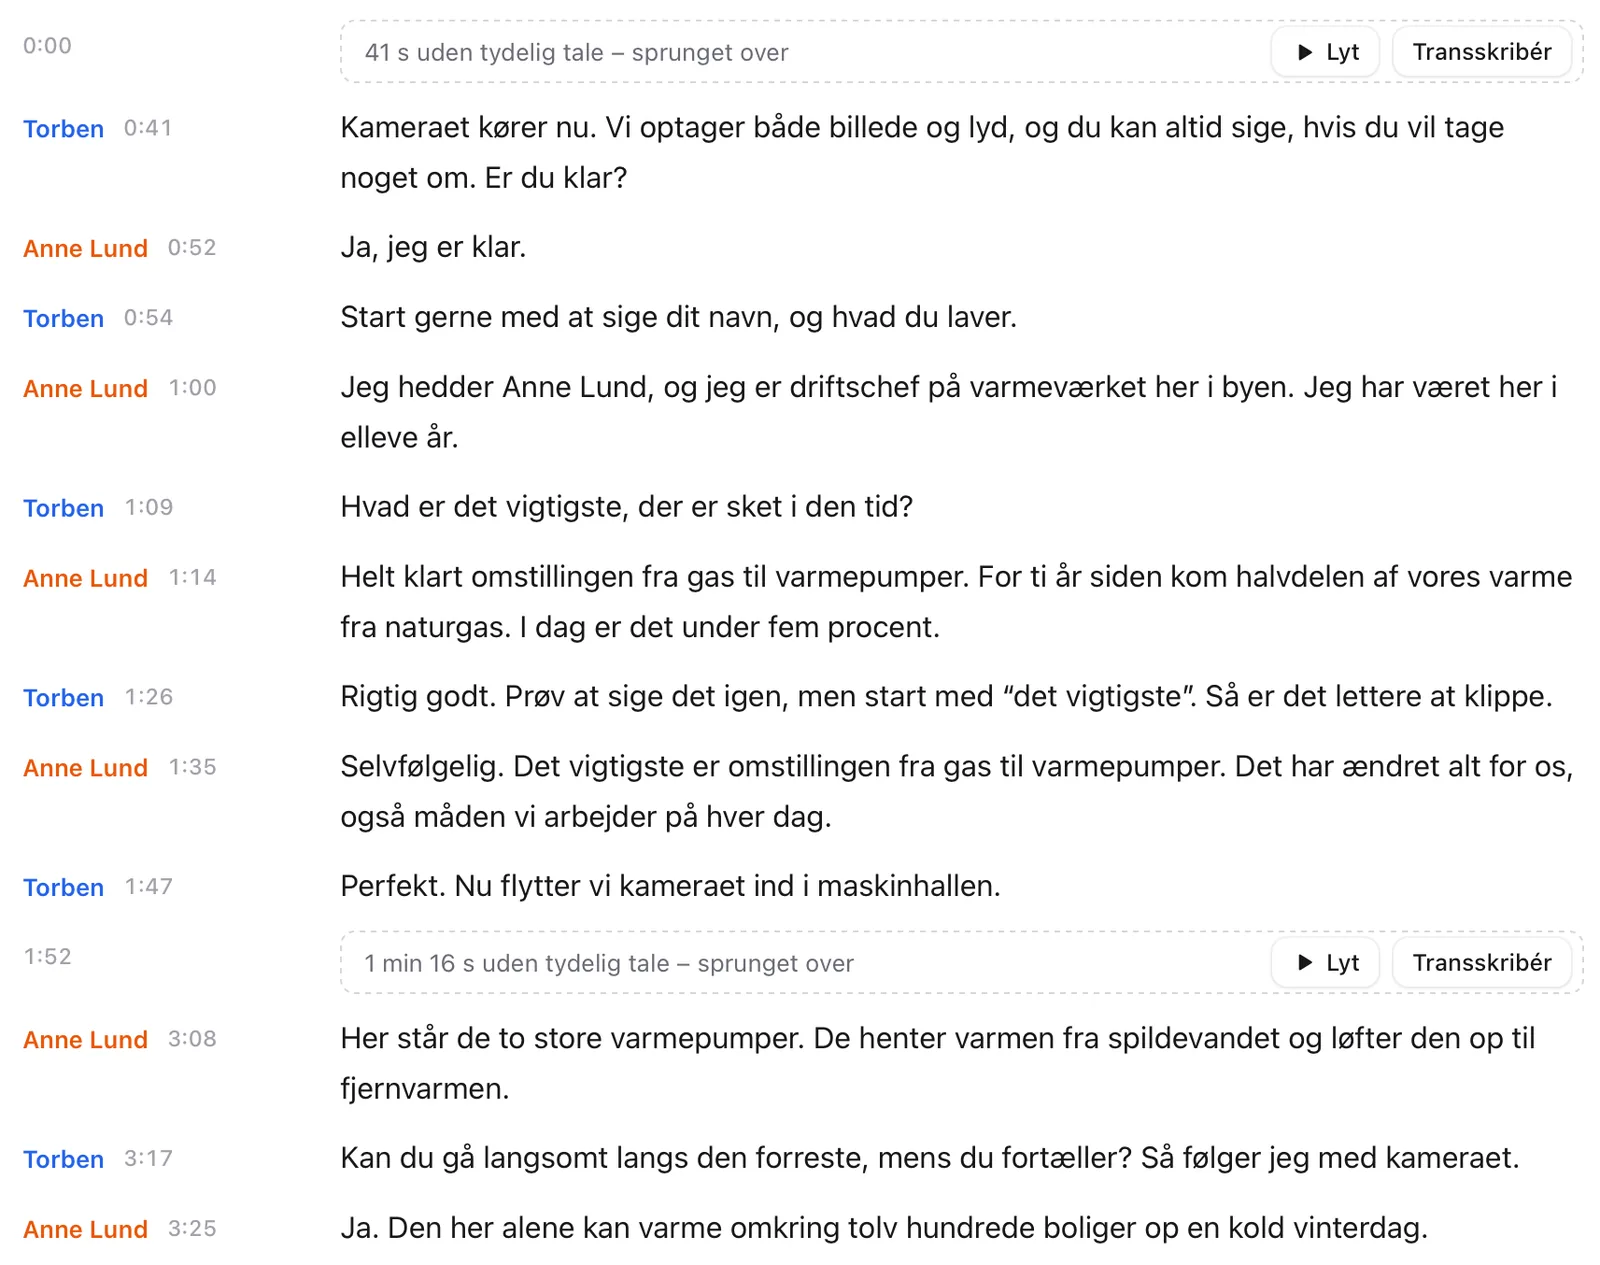
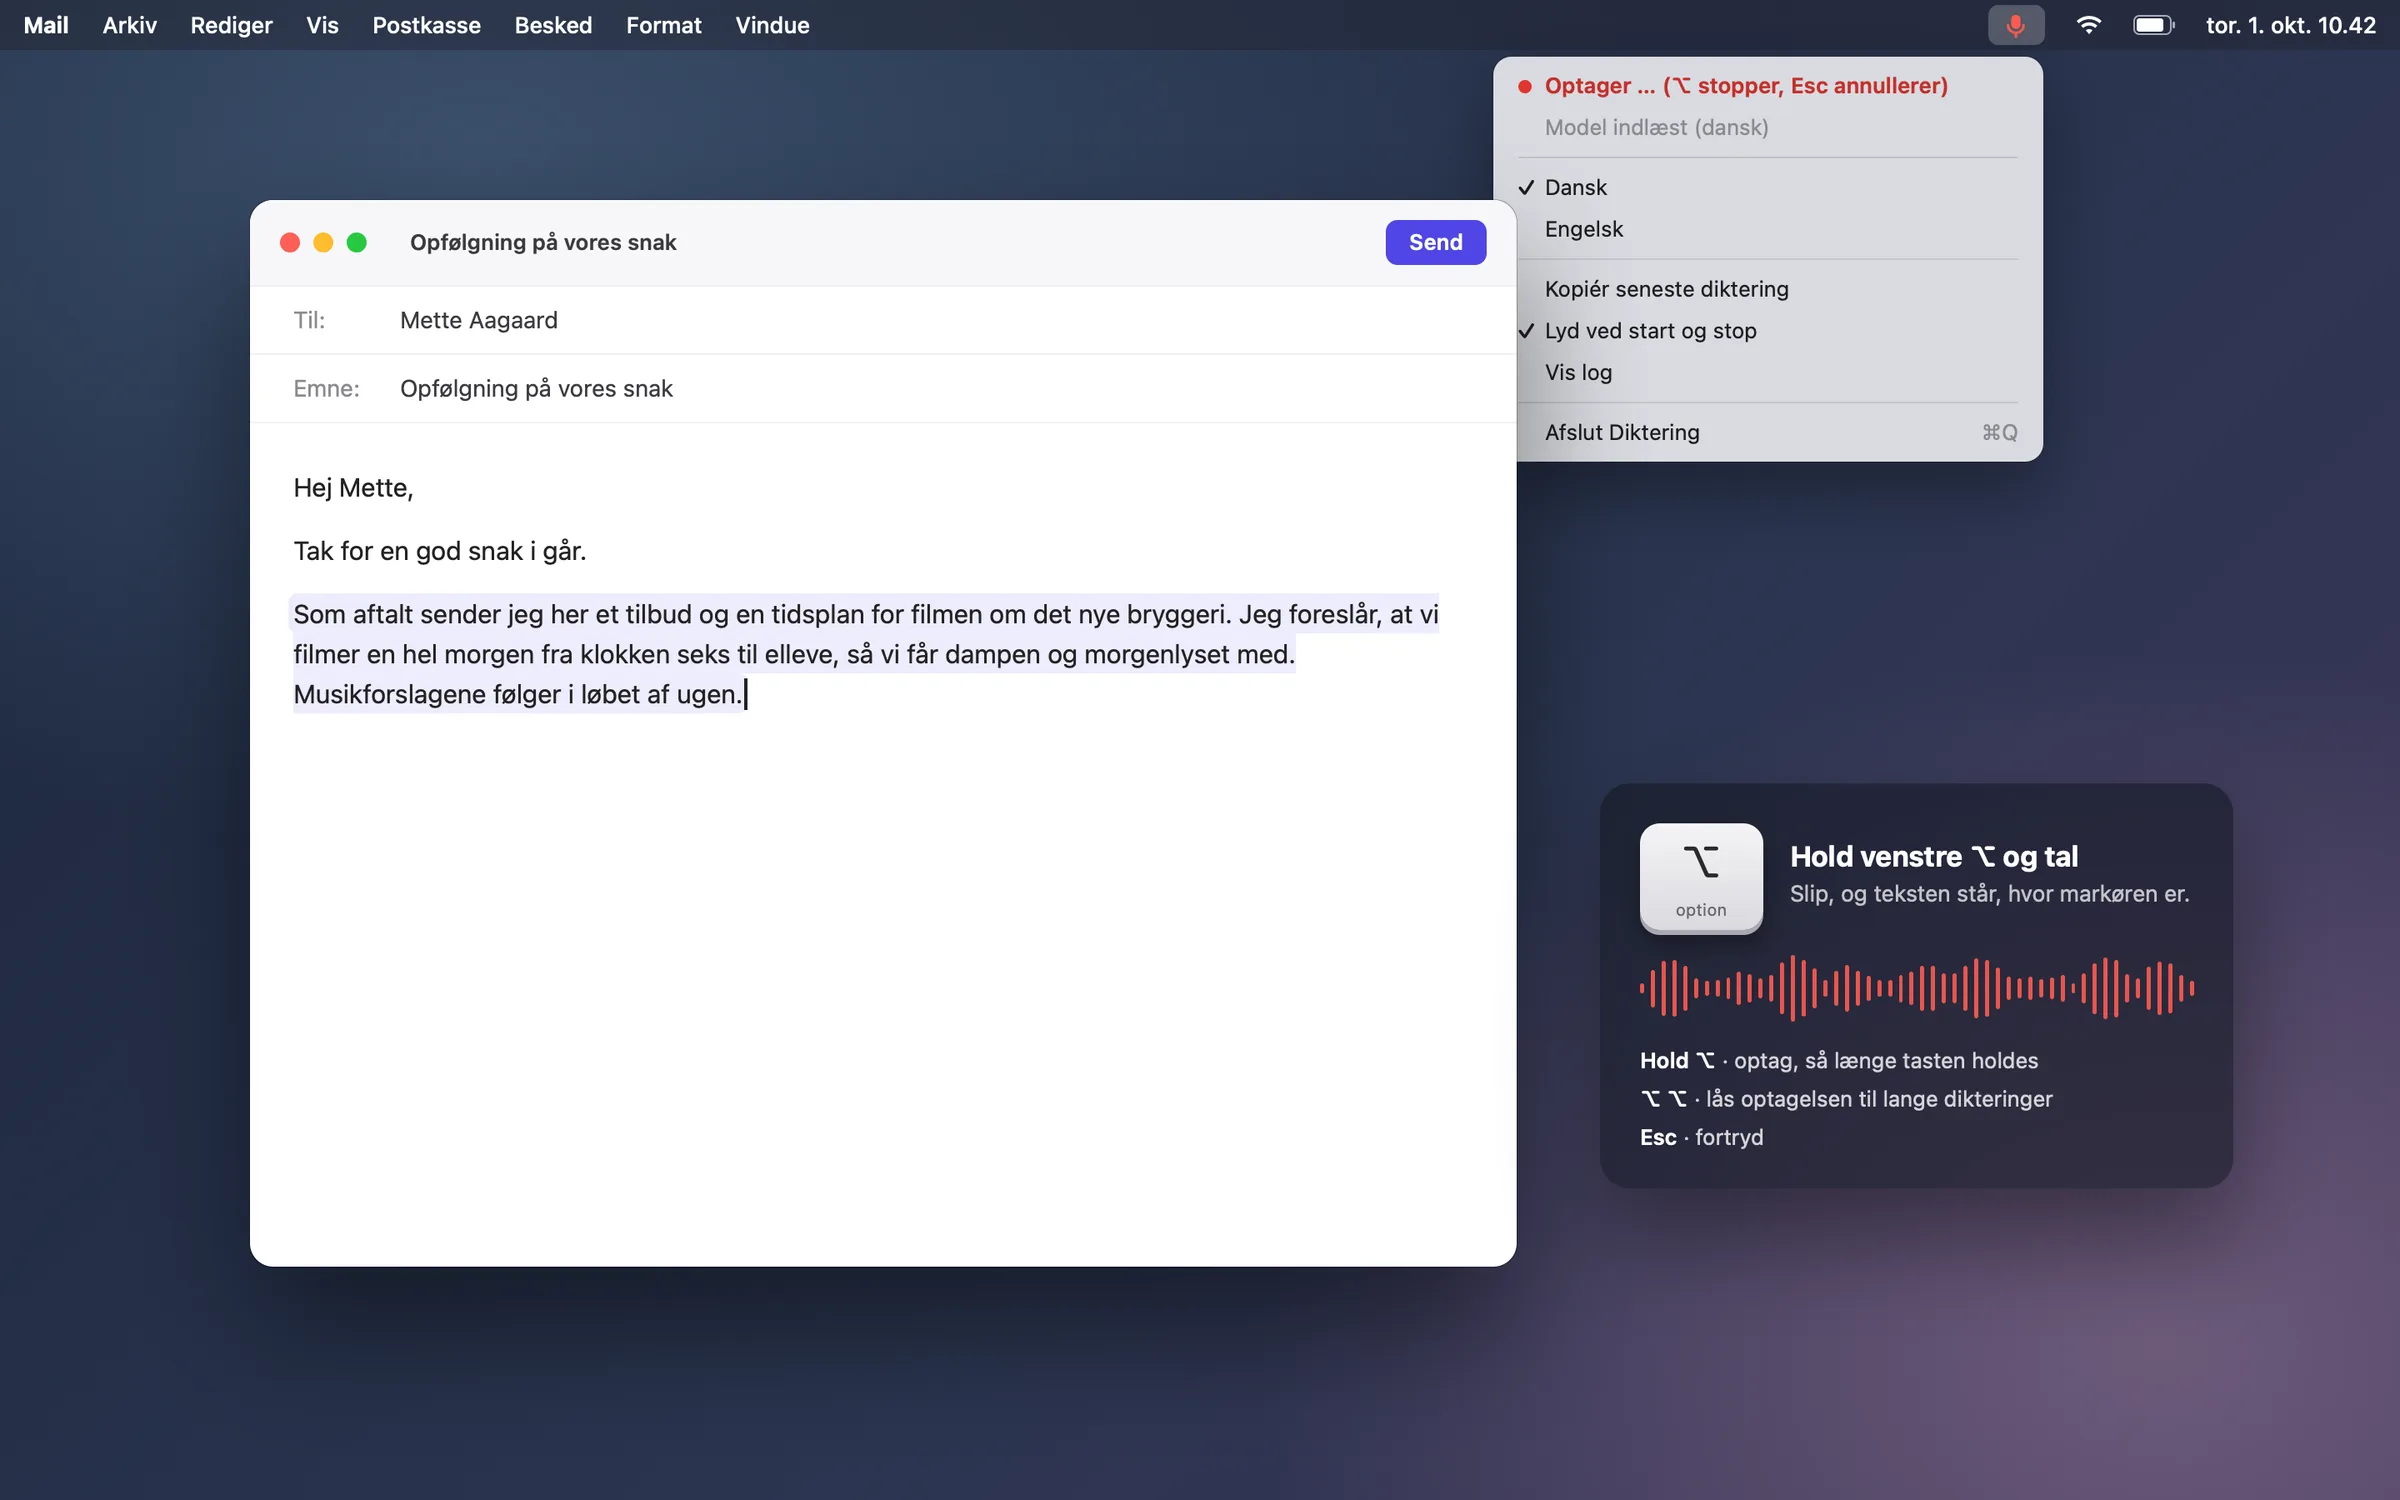
A selection of the choices that shaped the app. Several of them are a no to something that sounded like a good idea.
QuestionTestDecision
01
English
QuestionWhich model should transcribe English?
TestThree models on a 42-minute English recording. A blind listening test of the 40 biggest disagreements: Parakeet was right 24 times, the two Whisper variants 6 times each.
DecisionParakeet for English. The Danish Whisper model for Danish, as it also handles English passages without translating them.
02
Silence
QuestionWhisper invents text when nobody is speaking.
TestOn one recording the model wrote "Ace." 337 times during four minutes of silence. Three fixes tested; two of them also removed real speech.
DecisionCautious speech detection before transcription. Anything skipped is shown in the text, so you can listen and include it.
03
Vocabulary
QuestionCan the model spell names correctly if it gets them in advance?
TestNames given to the model as a prompt, both as a list and as a sentence: 20–50 words disappeared, invented sentences appeared, and the name was not fixed.
DecisionDropped for the model. The vocabulary is sent to the language model in the export instead, where it actually helps.
04
AI clean-up
QuestionShould a language model clean up the text automatically?
TestErrors that a language model turns into something plausible become invisible to anyone who doesn't read the full text themselves.
DecisionDropped. The export leaves the text unchanged but tells the language model which kinds of errors to expect.
05
Dictation
QuestionWhich engine gives the fastest dictation without losing accuracy?
TestSeven variants of two engines on 12 clips. An 8-bit version of the model produced text identical to the original on every clip, at half the size.
DecisionThe 8-bit model on the Mac's GPU. The alternative engine (whisper.cpp) was uninstalled again.
06
Speed
QuestionWhy does a short dictation suddenly take 18 seconds?
TestThe measurements showed it wasn't the model: other apps had pushed it out of memory.
DecisionLower memory use (1.8 → 1.0 GB) and a warm-up that runs while you speak.